Place every element before you generate
Draw color-coded boxes on the Studio Canvas, describe what belongs in each one, and let FLUX.3 Klein or MOSS-Image compose the frame around your layout. No ControlNet. No masking pass. No prompt roulette.
Local on Apple Silicon · 0–1000 coordinate grid · up to 10 boxes · 100% offline
Virtual Boxes are on-canvas layout regions. Each box has a normalized position and a short description. The model places the described person, object, background, or text inside that region instead of guessing from the prompt alone.
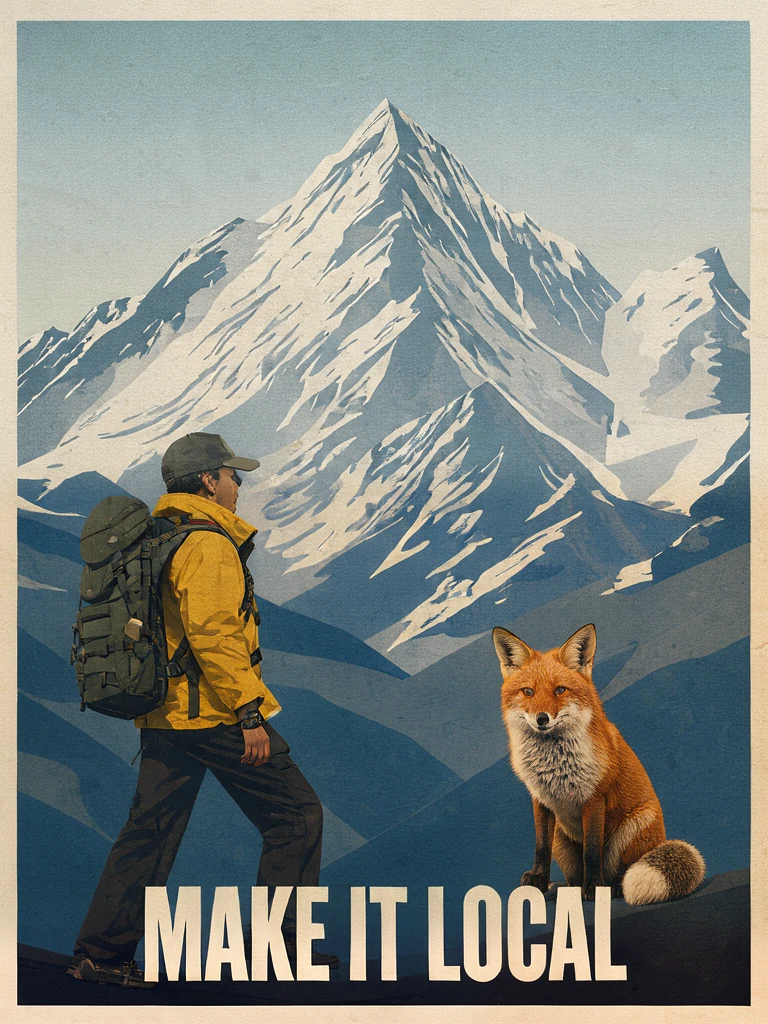
One FLUX.3 generation. Four declared regions.
Draw, describe, generate
The boxes are layout instructions, not a hard mask. They define where an element should live and how large it should be; the model still composes the pixels.
Add a box
Click [+] Box on the Studio Canvas and drag it into place. Each box gets a color and an ID such as person_1.
Say what is inside
Write a short description: “a hiker in a yellow jacket, standing, looking toward the mountain.” Text boxes take exact copy.
Compose the frame
The backend serializes the layout into the model's native prompt format. FLUX.3 places each element; MOSS uses its layout JSON.
Boxes are structured data, not magic
Coordinates are [ymin, xmin, ymax, xmax] on a 0–1000 grid. The same payload works through the local API or the Studio Canvas.
[
  {
    "id": "mountain_1",
    "bbox": [0, 0, 620, 1000],
    "desc": "Snow-capped mountain,
             geometric shapes"
  },
  {
    "id": "person_1",
    "bbox": [420, 70, 960, 430],
    "desc": "Hiker in a yellow jacket,
             looking at the mountain"
  },
  {
    "id": "fox_1",
    "bbox": [600, 620, 880, 900],
    "desc": "Red fox sitting upright"
  },
  {
    "id": "En_Text_1",
    "bbox": [840, 180, 960, 820],
    "desc": "MAKE IT LOCAL in bold
             condensed cream lettering"
  }
]
{
  "model": "flux3-klein",
  "prompt": "A bold retro travel poster
              on textured paper. A hiker
              <person_1> stands left, a red fox
              <fox_1> sits right, a mountain
              <mountain_1> fills the background.
              The text <En_Text_1> reads
              MAKE IT LOCAL at the bottom.",
  "width": 768,
  "height": 1024,
  "steps": 16,
  "spatial_boxes": [ … four boxes … ]
}
Three local models, one layout language
| Model | Layout path | Best for | Boxes |
|---|---|---|---|
| FLUX.3 Klein 5.6B | spatial_boxes → BFL box prompt | Posters, product scenes, exact text placement, multi-element composition | Yes, up to 10 |
| MOSS-Image SFT 5B | spatial_boxes → MOSS layout JSON | Storyboards, character blocking, object layout, Virtual Boxes HUD | Yes, up to 10 |
| Kromoss 5B (new in v0.5.0) | spatial_boxes → MOSS layout JSON | Artistic style, moody lighting, character blocking, spatial layout | Yes, up to 10 |
Virtual Boxes are not ControlNet. No separate depth, edge, or pose model is loaded. See the MOSS pipeline for the layout JSON path, or the agentic API for programmatic generation.
Layout control is useful when composition is the job
Poster and cover art
Place a subject, a background, and exact title text in one generation. No compositing pass in Photoshop.
Product scenes
Put the bottle left, the jar right, and the ingredient sprig front. Keep the arrangement stable across a batch.
Game UI and HUD
Reserve boxes for a character, health bar, inventory icon, and label. Iterate the art without moving the interface.
Storyboards
Block a character, prop, and caption in a frame, then generate variations of the same composition.
Virtual Boxes are API fields too
An autonomous agent can drive Virtual Boxes programmatically via the Agentic REST API (POST /api/generate with spatial_boxes). The reference covers spatial_boxes, polling, and image retrieval.
Virtual Boxes, answered
What are Virtual Boxes in DiffusionBear?
Virtual Boxes are on-canvas layout regions. Each box has a position on a normalized 0–1000 grid and a text description; the engine places the described element inside that region.
Do Virtual Boxes require ControlNet?
No. FLUX.3 Klein and MOSS-Image accept box layouts through their text prompt, so no separate ControlNet model or preprocessor is loaded.
Which DiffusionBear models support Virtual Boxes?
FLUX.3 Klein 5.6B, MOSS-Image SFT 5B, and Kromoss 5B (new in v0.5.0) support spatial box layout control in DiffusionBear 0.5.0.
Can Virtual Boxes place text in an image?
Yes. FLUX.3 Klein supports text boxes with language-tagged IDs such as En_Text_1. Give the exact words in the description, then keep the box large enough for the lettering.